Generative AI products your users trust and actually use
RAG assistants, AI copilots and LLM features inside your product, grounded in your data, evaluated for accuracy and tuned for cost.
Get in touch
What is RAG (retrieval-augmented generation)?
Retrieval-augmented generation is a technique where an AI model first searches your own documents or database for relevant information and then uses that content to write its answer. It keeps responses accurate, current and cited without retraining the model on your data.
Adding a model to a product is easy. Making it accurate, fast, safe and affordable at scale is engineering. We build generative AI features that are grounded in your data, measured with real evaluations and designed for the user's workflow.
From a private knowledge assistant to an AI copilot inside your SaaS, we handle retrieval, prompts, evaluation, guardrails and the product UX around it.
Our offerings
Our senior teams combine proven frameworks, reusable accelerators and hands-on engineering to deliver results at speed and scale.
Get in touch- 01
RAG knowledge assistants
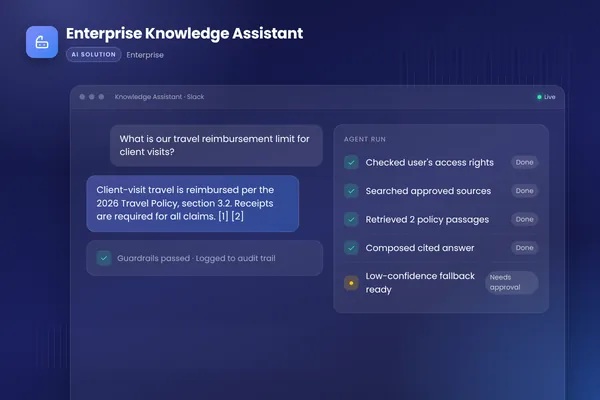
Chat with your documents, wikis, tickets and databases, with citations and access control.
- 02
AI copilots in your product
Context-aware assistants that draft, summarize, analyze and act inside your app's UI.
- 03
LLM integration & APIs
Add summarization, classification, extraction and generation to existing software.
- 04
Fine-tuning & evaluation
Custom evaluation sets, prompt optimization and fine-tuning when it beats prompting.
- 05
Voice & multimodal AI
Voice agents, speech-to-text, image understanding and document vision features.
- 06
AI governance & guardrails
PII redaction, content filters, prompt-injection defense and usage analytics.
BufferSol's Generative AI & LLMs delivery approach
- 01
Use-case & data review
Validate the user job, data quality and success metrics before writing code.
- 02
Evaluation-first build
Create a test set, then iterate retrieval, prompts and models against it.
- 03
Productize
Streaming UX, feedback loops, guardrails, caching and analytics.
- 04
Operate
Monitor quality, latency and cost; upgrade models as better ones ship.
Industry-specific Generative AI & LLMs solutions
Education
Tutoring assistants and content generation aligned to curriculum.
Legal & compliance
Contract review, clause extraction and policy Q&A with citations.
Media
Content tagging, summarization and personalized recommendations.
SaaS
Natural-language search, report builders and in-app assistants.
Why BufferSol for Generative AI & LLMs?
Answers you can verify
Grounded, cited responses from your own content reduce hallucinations and build user trust.
Differentiated product
AI features that solve real user jobs make your product stickier and easier to sell.
Predictable cost
Caching, routing and right-sized models keep per-request costs low as usage grows.
Secure, responsible delivery
Least-privilege access, audit logs and security reviews on every release.
100% IP ownership
You own the code, designs and data. Documented handover, no lock-in.
Senior team, no hand-offs
The engineers who scope your project are the ones who build it.
Technology we use
- Claude
- OpenAI
- Gemini
- Llama
- LangChain
- LlamaIndex
- Pinecone
- pgvector
- Vercel AI SDK
- Next.js
Enterprise-ready by default
Security, governance and responsible AI
Autonomous systems only create value when you can trust them. Every agent and platform we ship includes the controls your security, legal and compliance teams expect.
Security by design
Least-privilege access, encrypted data in transit and at rest, secrets in managed vaults and OWASP-aligned code reviews.
Human-in-the-loop AI
Approval gates for high-impact actions, confidence thresholds and clean hand-offs to your team when an agent is unsure.
Guardrails & audit trails
Every agent decision, tool call and data access is logged and traceable, so compliance teams can review what happened and why.
Evaluation & monitoring
Test suites for prompts and models, cost and latency dashboards, and drift alerts before quality slips in production.
Data privacy & compliance
GDPR-ready data handling, NDAs as standard, data residency options and HIPAA-conscious builds for healthcare.
You own everything
Full IP transfer, source code in your repositories and documentation your in-house team can run with.
Related case studies
Generative AI & LLMs solutions we have designed, built and put into production.
How we engage
Engagement models built around outcomes
Start small, prove value fast and scale what works, with transparent pricing at every stage.
2–3 weeks
AI Discovery Sprint
Map your processes, rank automation opportunities by ROI and leave with a working prototype and a costed roadmap.
- ✓Process & data audit
- ✓Use-case scoring
- ✓Clickable or working prototype
- ✓Fixed price
6–16 weeks
Build & Launch
A dedicated squad designs, builds, tests and launches your agent, workflow or product, with weekly demos and a fixed scope.
- ✓Product, design & engineering
- ✓Weekly demos
- ✓QA, security & evaluation
- ✓Production launch
Monthly
Run & Scale
We operate, monitor and improve what we built: model updates, new automations, SLAs and 24/7 support.
- ✓Monitoring & evaluation
- ✓Continuous improvement
- ✓SLA-backed support
- ✓Dedicated team option
Will our data be used to train AI models?
No. We use enterprise API terms that exclude your data from model training, and can deploy in your own cloud account or with private, self-hosted models when required.
How do you reduce AI hallucinations?
We ground answers in retrieved sources, require citations, restrict the model to approved content, add confidence thresholds and measure accuracy on an evaluation set before every release.
Should we fine-tune a model or use RAG?
Most business use cases start with RAG because it keeps answers current and auditable. Fine-tuning helps when you need a specific style, format or a smaller, cheaper model for a narrow task. We test both on your data.
Can you add AI features to our existing app?
Yes. We integrate LLM features into existing web and mobile products through APIs, without a rewrite, and design the UX so users adopt them.
What does it cost to run generative AI in production?
It depends on volume and model choice. We design for cost from the start with caching, model routing and prompt optimization, and provide a cost-per-request estimate before launch.
Explore more services
All servicesGet in touch
Let's build what's next, together.
Tell us what you want to automate or build. A senior engineer will reply within one business day.
Request a free consultation